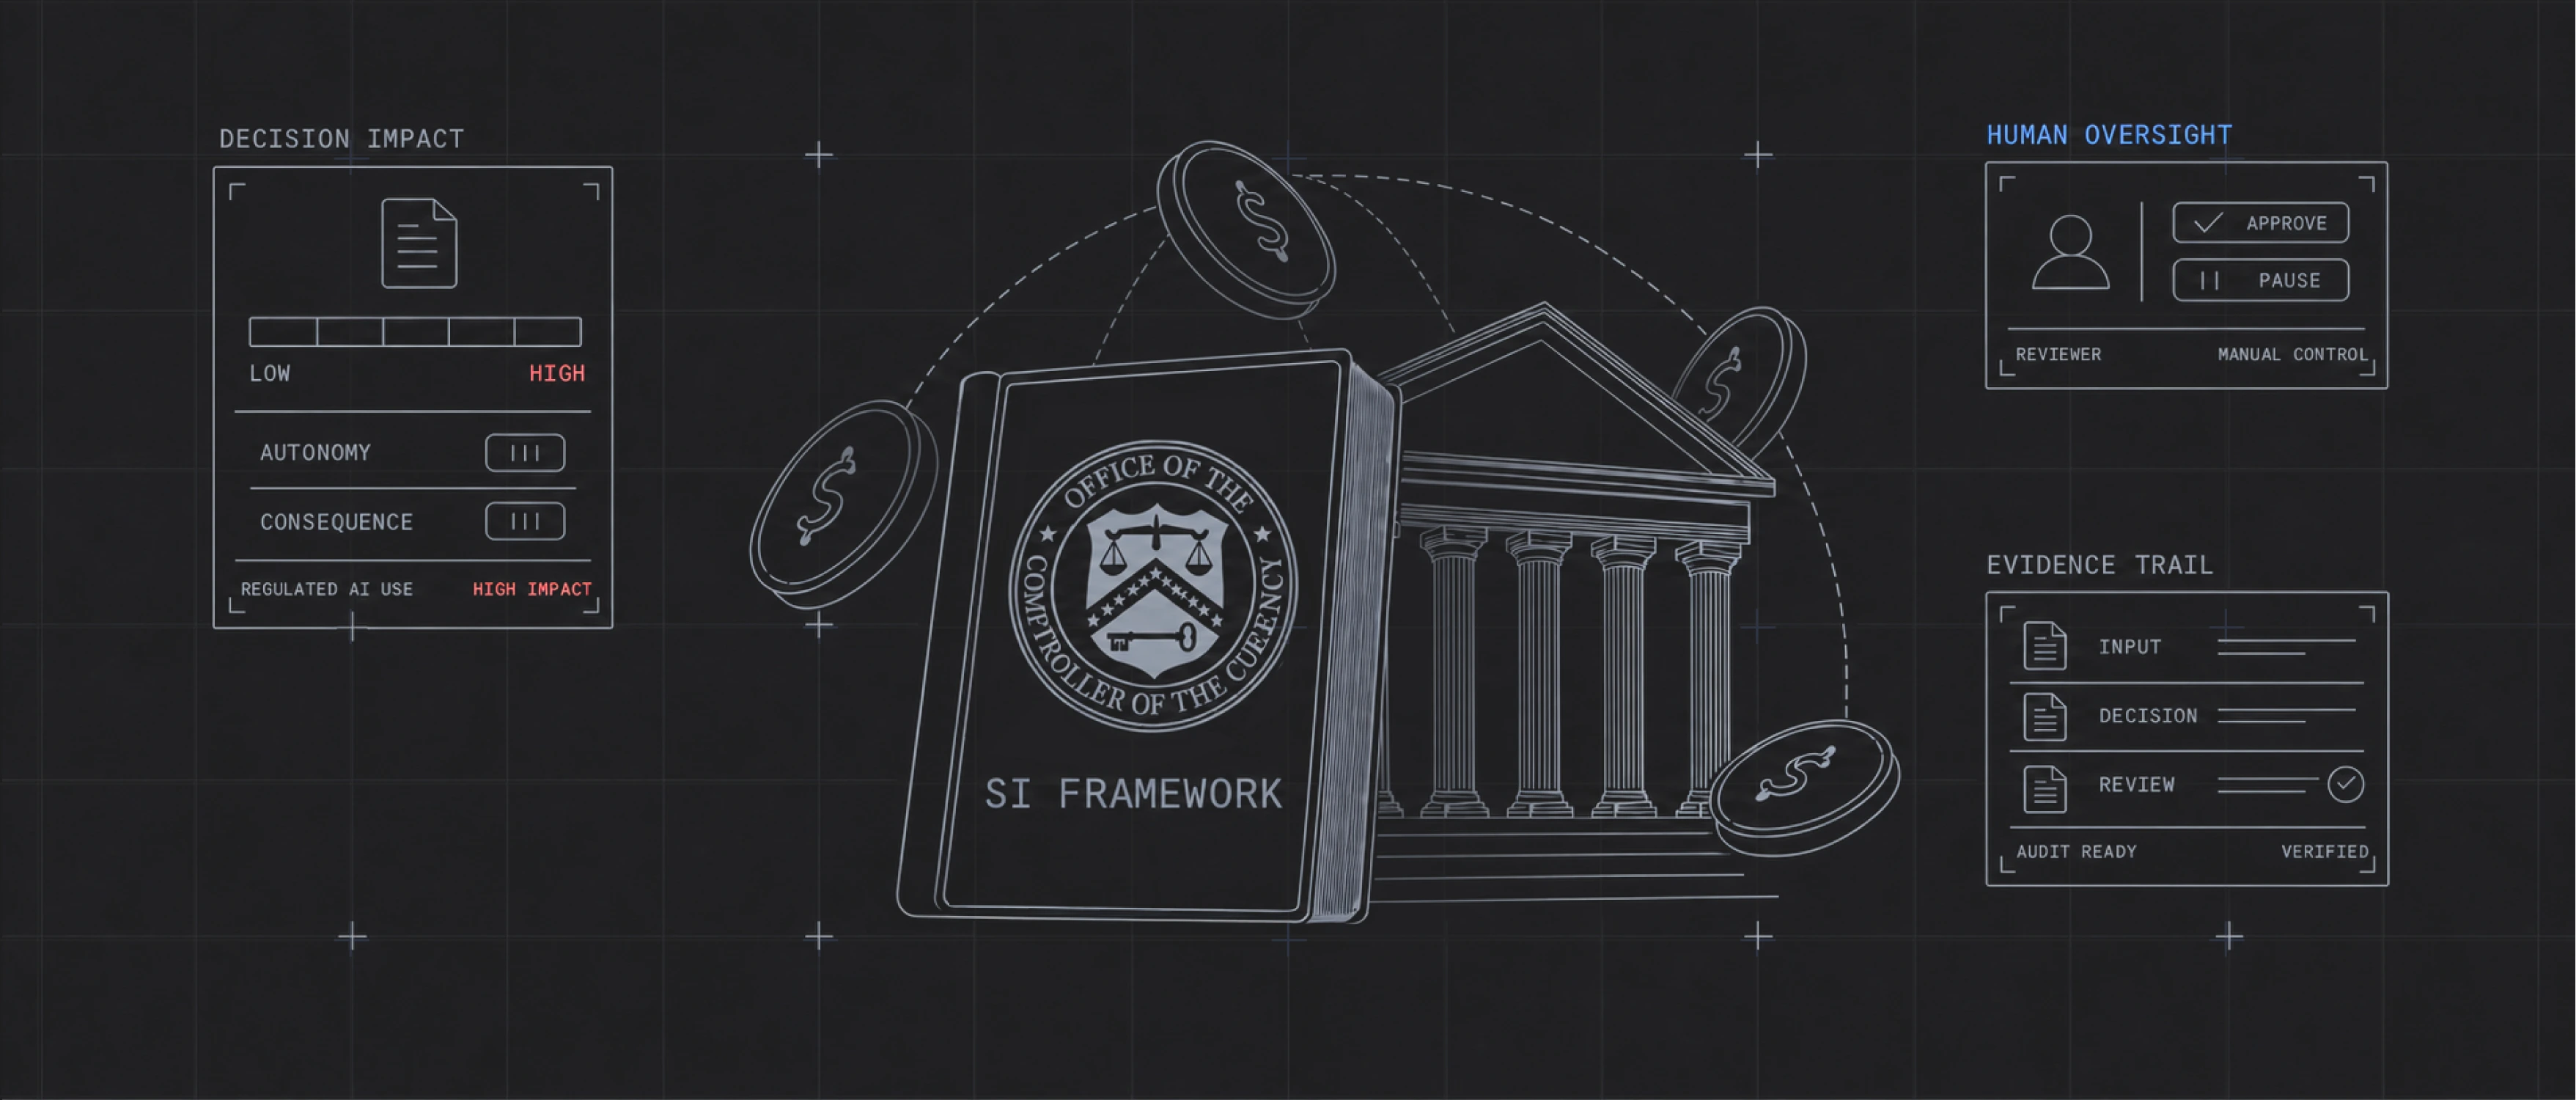
On November 4, 2026, the OCC gave its examiners a new way to assess how banks use AI. The Supervisory Framework for Bank Use of Super Intelligence (SI), the OCC’s term for what most of the industry calls AI, asks examiners to judge each system by the consequences of the decisions it influences and the strength of the human oversight around it. Examiners should focus their attention on the uses that carry the most consequence, whatever their technical complexity. For financial crime teams, that standard raises a pointed question about whether any model in AML and sanctions compliance truly carries low consequence.
The framework has neither the force of regulation nor the status of standalone supervisory guidance. It works within existing risk-management disciplines. Much like the FFIEC BSA/AML Examination Manual, it gives examiners a starting point for evaluating AI within a bank’s existing governance, compliance, technology, and operational-risk practices. The OCC describes it as a living document that supports risk-based supervisory judgment, so banks should read its illustrative considerations as signals of where examiners will focus. Generative and agentic AI remain outside the scope of SR 26-2.
The OCC treats AI as a technology that can introduce or amplify existing risks, and examiners will assess it within a bank’s existing risk categories. Banks also do not need to define a separate risk appetite for AI. What the framework adds is a clear view of the questions examiners are likely to ask and the evidence banks will need to answer them. It also gives financial crime teams room to apply controls proportionately, in keeping with a risk-based approach.
Consequence drives examiner scrutiny
The key consideration for examiners is consequence. The framework asks examiners to identify high-consequence uses, which may not necessarily be the most complex. There is a subtle shift in thinking here. Up to now, much of the conversation has focused on explainability; examiners have consistently cautioned against the use of “black box” AI, and have warned banks that they will need to be able to explain the decisions being made by these tools. This guidance keeps that concern in place, and its outcome-driven approach broadens the assessment of risk beyond explainability. Understanding the model’s inputs, limitations, and behavior remains important, but those considerations need to be evaluated alongside what the system can do, whose decisions it influences, and how difficult an error would be to reverse.
The framework illustrates consequence with an example tiering method and leaves final classification to each bank. Section 2.2 lists the relevant factors, including decision consequence, reversibility, customer and financial impact, autonomy, data sensitivity, explainability, and interdependencies. Banks will need to identify what they believe to be the most consequential decisions their models make, and classify them accordingly.
The factors leave room for judgment in financial crime use cases. For instance, an information-gathering bot may be ranked as lower in consequence, given that it makes no decisions. However, if the bot is consistently missing material information when pulling data and documents together, that may have a significant impact on the investigation. Similarly, if an AI is built to draft SAR narratives, but consistently fails to provide relevant data in the narrative itself, this could result in law enforcement not getting information needed to act.
Financial crime teams can still rank some models as lower consequence, provided every model has clear governance documentation that outlines what the risks are, what compensating controls are in place, and how these controls are being tested to ensure they are working as expected, as well as what action will be taken if they are not. Section 2.1 of the framework details this, noting that banks
“…may document what an SI system or agent is designed to do, what it is not designed to do, who or what may invoke it, the data and systems it is permitted to access, the actions it could take, and the circumstances that may require human review or suspension.”
Permissions act as controls in their own right. Data access, connected tools, account privileges, and permitted actions are substantive controls that determine what the system can actually do, and what can happen when it fails. These should all be part of the documentation of each model the bank uses.
Human oversight must be more than a check
The framework distinguishes between human-in-the-loop and human-on-the-loop oversight. The former involves approval before an output or action is used, while the latter refers to active monitoring, with the authority and practical ability to intervene. The appropriate level of oversight should reflect the consequences of the decision.
Importantly, the OCC looks beyond whether a human approval step exists. It raises questions about nominal approvals, bulk review, alert fatigue, and whether one person can realistically oversee the assigned activity. Reviewers need the expertise, supporting information, time, and authority to reject, modify, pause, or stop the system.
Financial crime leaders increasingly worry that as teams depend more on AI, analysts will lose the skills needed to challenge its decisions. Going forward, banks will need to show that their people meaningfully reviewed the AI’s output, and provided an effective challenge where warranted. Just clicking the submit button to confirm the AI’s decisioning will not be enough. Teams will need to build checks into the workflow to monitor for analysts rubber-stamping AI decisions.
Retaining those skills also matters when the system needs to be taken offline. A bank may have the technical ability to stop an agent, but it also needs to show that investigations, screening, and reporting can continue without it. A fallback process is only credible if the people expected to operate it still have the knowledge and capacity to do so.
Broader implications for model risk management
The framework complements the revised interagency model risk management (MRM) guidance issued through SR 26-2 and OCC Bulletin 2026-13, which emphasizes MRM tailored to the institution’s risk and model usage. The OCC framework adds considerations particularly relevant to generative and agentic systems.
One of the clearest connections is effective challenge. SR 26-2 describes critical analysis by objective experts who can effect change. As described above, the OCC’s treatment of human oversight applies a similar principle in day-to-day operations, where review must influence outcomes when warranted. Operational review and independent model challenge remain distinct controls.
Section 2.5 also recognizes that traditional validation approaches may need to change. As noted, a consequence-based review will necessarily be more concerned with model output than with the complexity of the inputs and logic. Outputs can vary between runs, and changes to prompts or vendor systems can affect decisioning between periodic reviews. Conventional MRM champion-challenger comparisons may not be as effective when dealing with the constant change and improvements of AI models.
Repeated testing, expert reference sets, distributional measures, and more frequent monitoring may provide more useful evidence. Validation still matters, and banks should adapt it to how these systems operate.
Getting through MRM review is only the starting point. Financial crime teams should also define how they will assess performance in production, including material omissions, unsupported statements, false negatives, and exceptions. Faster investigations or fewer alerts do not, by themselves, demonstrate effectiveness. Monitoring should identify when performance has deteriorated enough to require review, reduced autonomy, or suspension.
Global regulators are converging on the same standard
The OCC framework arrives as regulators in Asia, Europe, and the international standard-setting community reach similar conclusions about AI governance. For institutions operating across jurisdictions, the overlap means a governance program built to one of these standards will address much of what the others expect.
- Singapore’s MAS emphasizes inventories, use-case materiality, proportionate lifecycle controls, meaningful human oversight, and accountability for third-party AI.
- The EU AI Act links obligations for legally defined high-risk systems to their purpose and use, including documentation, monitoring, and competent human oversight.
- The FSB’s final sound practices emphasize organization-wide governance, materiality assessment, lifecycle monitoring, explainability, and effective human oversight.
These instruments have different legal effects. The EU AI Act’s statutory categories, for example, differ from the OCC’s supervisory assessment of consequence. Still, the common direction is clear. Institutions should understand each use case, assess its risks, and demonstrate that their controls work.
Putting consequence-based classification into practice
The focus on consequence also parallels FinCEN’s April 2026 AML/CFT program rule NPRM, which directs attention and resources toward meaningful risk and effectiveness rather than technical compliance alone. FinCEN addresses illicit-finance program design; the OCC addresses AI failure and delegated authority. Both, however, ask institutions to demonstrate where risk actually lies.
Few financial crime models carry as little consequence as teams assume. Teams should classify each specific use case on its own merits, whatever the model or department behind it. The three examples below show how the same technology can carry very different levels of consequence.
- An assistant formats an investigator’s already-approved notes.
- A system drafts a SAR narrative that an investigator verifies against source records.
- An agent autonomously closes alerts or releases payments following sanctions review.
Each can fail, but the authority, reversibility, and potential harm differ. Even an apparently administrative summary can become consequential if investigators rely on it instead of reviewing the underlying evidence.
For financial crime leaders, the priority is to document those distinctions: identify the decision being influenced, assess the harm a failure could cause, limit the system’s authority, test whether reviewers can intervene, and retain enough evidence to reconstruct material actions.
The framework’s real value lies in its core expectation that institutions can explain precisely what they have delegated to AI and how they remain in control.